An AI-search experiment log that a small team can maintain
Build a report that distinguishes sampled visibility, accurate citations and attributable customer actions. Keep the raw observations so another person can reproduce the calculation.
In this article
Maintain a small experiment register
Measurement is useful when a lean international team can connect an observation to a release without claiming that one caused the other. Keep the question panel small enough to repeat across relevant markets and languages, record the answer and citation evidence, and note concurrent product or campaign changes. The goal is a durable decision log, not another dashboard that the team cannot maintain.
For each change, record the hypothesis, affected URLs, release date, owner and the next observation window. Keep the question panel stable while you make a bounded set of changes. If several releases overlap, acknowledge that attribution becomes harder.
A lightweight shared sheet may be enough at the start. Spend time on consistent definitions and retained answer evidence before buying elaborate tooling. The important output is a decision about the next release, including when the sensible choice is to stop an unproductive line of work.
Record releases before interpreting the chart
Keep an experiment register with the hypothesis, affected pages, release date and owner. Note other changes that could influence the same observations. When several updates ship together, acknowledge that you may only be able to assess the combined release. The register should make uncertainty visible instead of encouraging a story that assigns every favourable movement to the most recent agency task.
Use a maintainable evidence sample
Choose a question panel small enough for the team to inspect and repeat reliably. Keep exploratory questions outside the main comparison until you intentionally revise the protocol. Save raw answers and scoring decisions in an exportable format. A lightweight process consistently followed is more useful than an elaborate scorecard that stops being maintained when the growth team gets busy.
An illustrative visibility comparison
- 90 valid observations
- 18 mentions = 20%
- 27 mentions = 30%
- Difference: +10 percentage points
- Illustrative comparison, not a growth promise
Illustrative counts from comparable samples. This is not a forecast, causal estimate or reported client result.
Turn the review into the next release decision
Ask which observation supports a concrete change: a factual correction, clearer service explanation, better supporting evidence or a technical investigation. Put that action into the same backlog as other website work. If the evidence does not justify implementation, record the decision to continue observing or stop the experiment. This keeps GEO from becoming a separate reporting ritual disconnected from the team’s shipping capacity.
What to put on the comparison sheet
On narrow screens, scroll the table to see all columns.
| Measurement control | Evidence to retain | Acceptance record |
|---|---|---|
| Release register | Hypothesis, affected pages, owner and date | Every chart annotation maps to a real release |
| Concurrent changes | Product launches and unrelated site edits | Report possible confounders next to the result |
| Repeatable sample | Saved question set, settings and raw answers | Another team member can reproduce the calculation |
Use counts that can be audited
An illustrative panel contains 90 valid answer observations. If 18 mention the brand, the observed mention rate is 20%. If a comparable later panel has 27 mentions out of 90, it is 30%, a difference of 10 percentage points. These are example numbers, not a forecast or a reported client result.
The calculation is simple; the interpretation is not. Repeated answers to related questions are not necessarily independent observations. A small panel does not represent the entire audience. Show the counts, failed runs and question composition alongside the rate so the reviewer can see what actually changed.
Separate mentions, sources and accuracy
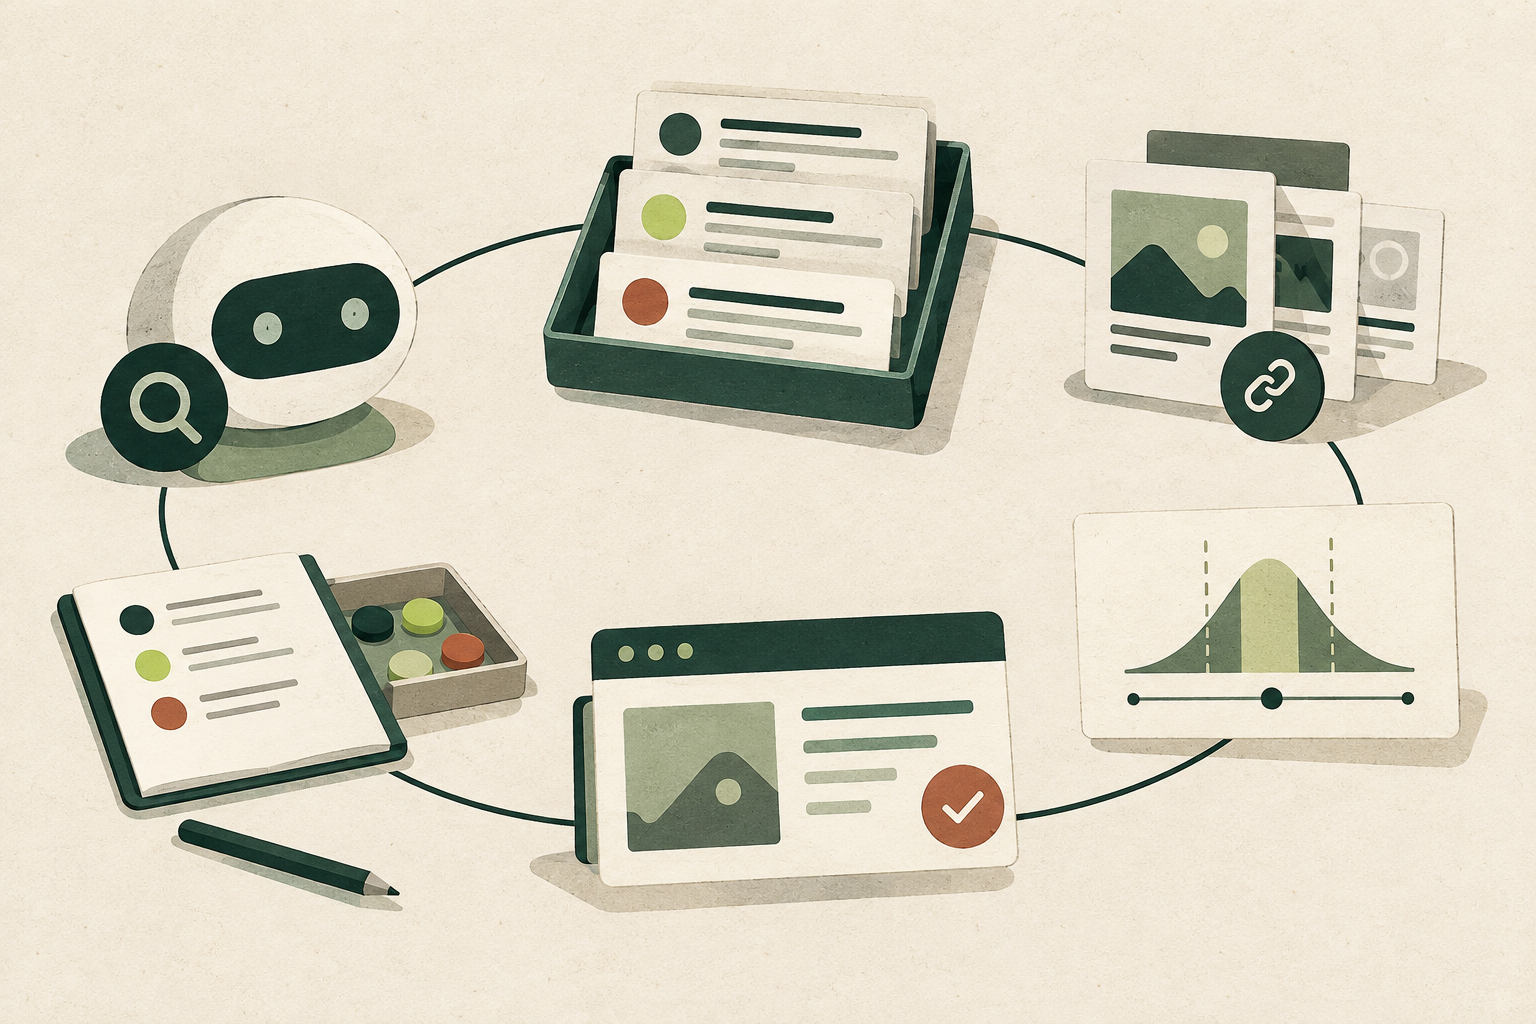
A brand can be mentioned without a link, linked without being recommended, or recommended with an incorrect claim. Define these outcomes before scoring. Preserve the source URL and relevant answer passage so a reviewer can check whether the cited page supports the statement.
Track important factual errors as a separate work queue. Correct the public information you control and record requests concerning other sources. Do not count a correction request as a completed correction. The report should distinguish what the agency changed from what a third-party platform later displayed.